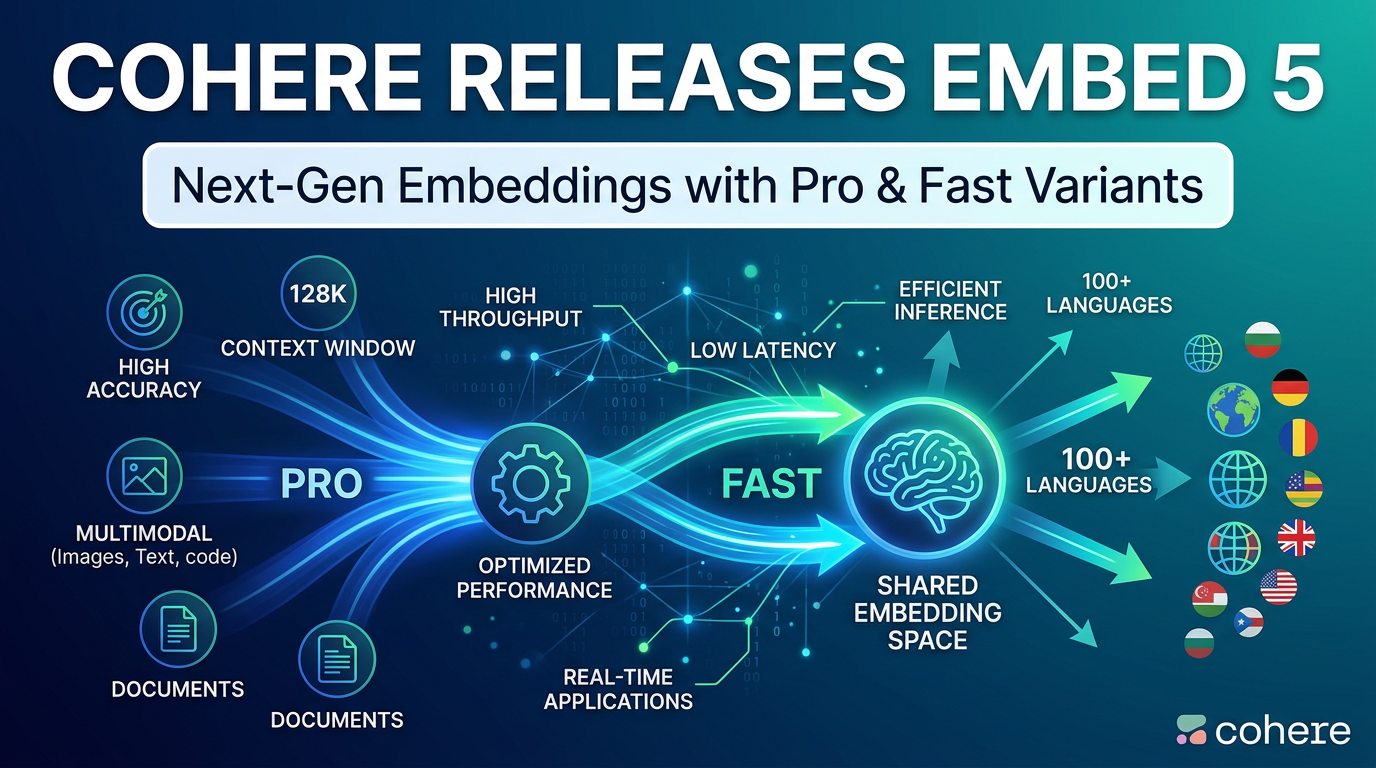
Cohere announced Embed 5, a new embedding-model family designed for enterprise retrieval, on October 2, 2026. The release adds multimodal inputs, a 128,000-token context window, more than 100 supported languages, and two model variants optimized for different retrieval workloads.
Two variants
Embed 5 Pro targets the highest retrieval quality, particularly for offline indexing and quality-sensitive systems. Embed 5 Fast is designed for low latency and high throughput, making it suitable for interactive search and agent loops.
Shared embedding space
A notable design choice is that Pro and Fast share an embedding space. Cohere recommends using Pro for indexing and Fast for live queries. Because both variants can operate in the same space, teams can change the query-side model without rebuilding the entire corpus, provided compatible dimensions are used.
Multimodal retrieval
Embed 5 can represent text, images, and mixed text-and-image inputs such as PDF pages in a single vector representation. This can simplify retrieval systems that need to search documents where important information is split between written content, charts, screenshots, and other visual elements.
Storage flexibility
The model supports Matryoshka dimensions from 256 to 2048 and float, int8, and binary output types. That gives teams room to trade storage size, memory use, retrieval quality, and serving performance according to workload requirements.
Practical takeaway
Teams building RAG or agent retrieval should benchmark Embed 5 using their own documents, especially PDFs and multilingual data. Compare indexing cost, query latency, vector storage, recall, and downstream answer quality rather than choosing an embedding model from benchmark numbers alone.